Monitor adapt and communicate: Difference between revisions
No edit summary |
No edit summary |
||
| Line 53: | Line 53: | ||
== Say what you found, including when nothing moved == | == Say what you found, including when nothing moved == | ||
<div class="sump-lead-fig">[[File:Broadcast.svg|frameless|link=|alt=| | <div class="sump-lead-fig">[[File:Broadcast.svg|frameless|link=|alt=|600px]]</div> | ||
Communication is the third part of this step and the one most easily postponed. Four audiences have a claim on the results. The councils that each adopted their own part of the plan need to see their own commitments tracked, in the form they voted on. The coalition needs enough detail to keep making decisions together. The operator needs the usage picture early enough to act on it. And residents, who were told a service was coming, need to hear how it went, including from an area where a previous promise was not kept. | Communication is the third part of this step and the one most easily postponed. Four audiences have a claim on the results. The councils that each adopted their own part of the plan need to see their own commitments tracked, in the form they voted on. The coalition needs enough detail to keep making decisions together. The operator needs the usage picture early enough to act on it. And residents, who were told a service was coming, need to hear how it went, including from an area where a previous promise was not kept. | ||
Revision as of 10:15, 19 October 2026
Step 11 of 12 Implementation & Monitoring
The measures are running, and this step turns them into a loop. It asks whether the improvement is arriving, what to change where it is not, and how to tell people either way. Monitoring is the routine tracking of the indicators fixed earlier, evaluation is the harder question of why the readings look the way they do, and communication is what keeps the support that the next round of the plan will need. What DREAMS adds here matters most in the outskirts. Because the baseline was measured for named groups using their own thresholds, the same measurement can simply be run again, which turns the plan's central question into something answerable rather than assertable.
Ask the same question again
The diagnosis did more than map the area. It measured the neighbourhood twice, once against a textbook standard and once with the amenities a named group weights most and the walking times they said they accept. Geretsried in the Munich lab shows what that leaves you holding.
Those figures come from Deliverable 3.1, and the useful thing about them is that they are reproducible. Run MinuteMap again on the configuration that now exists, holding the preference set, the amenity list and the time thresholds exactly as they were, and the difference between the two runs is the answer to the question the plan was written to settle. Not whether the area improved on average, but whether it improved for the group whose access was worst.
Two disciplines make that comparison worth anything. Hold the method fixed and let only the world change, which means recording the model version, the data sources and the date of every run because an amenity list rebuilt from newer data will move the score on its own. And read the amenity-level figures rather than only the headline. A single composite number is slow and blunt, while the components underneath it are where a new grocery or a new bus stop actually registers.
One honest limit. A model re-run tells you whether something is reachable, not whether anyone goes. The survey side of the diagnosis is what answers the second question, and the two belong in the same report.
Outputs move first, outcomes move later
DREAMS sorts every indicator into one of two kinds. An output indicator describes the intervention itself, meaning the thing exists and is being used. An outcome indicator describes the change the project was for. The distinction sounds academic until you watch the two behave differently in time (Deliverable 6.1).
The flexible activity hub set up in Liesing was judged on both kinds at once. Its output targets were countable and immediate, meaning two events or offers a week, at least ten visitors on a day with activity, a hundred visitors at a film or theatre evening, and three local organisations drawn into preparing the programme. Its outcome targets were the actual ambition, meaning a fifth off the travel time residents need to reach cultural offers, four in five visitors arriving on foot or by bike, and a corresponding fall in the carbon of those trips. The bike-sharing station beside it was set up the same way, with weekly pick-ups as the output and satisfaction and carbon as the outcomes.
Outputs arrive within weeks and outcomes often arrive after the pilot money has run out, so a report that carries only one of them will mislead in a predictable direction. Early reporting that leans on outputs sounds like success. Later reporting that leans on outcomes sounds like failure. Carry both from the first review, label which is which, and resist the substitution that comes naturally under pressure, where a healthy usage figure is offered as evidence that access improved. Strong outputs beside flat outcomes usually mean the service has been discovered by people who were already reasonably well served, which is worth knowing early and is fixable.
Measure while it is running
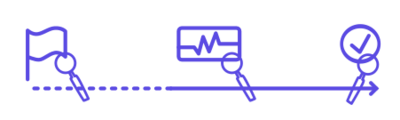
DREAMS collects at three moments, before the intervention, during it and after it. The middle one is the one cities most often skip and the one this step depends on, because a design that only compares a before with an after tells you nothing until the money is spent and the decision is behind you (Deliverable 6.1).
The readings taken during the run are usually cheap, being operator data that already arrives, manual counts on days when something is open, and short feedback forms handed out while people are there.
When a reading disappoints, ask three questions before touching the measure. Was it delivered as designed, which the delivery record from the previous step should answer in a line. Is the indicator sensitive enough to have registered a change of the size this measure could plausibly produce, which is the test applied when the indicator was chosen and worth applying again now. And is the measure reaching the group it was written for, which requires breaking the reading down rather than reading the area average. Only after those three does adaptation become a decision rather than a reflex. Then choose plainly between adjusting the measure, extending it to gather more evidence and stopping it, and record which you chose and why, because the reasoning is what the next cycle inherits.
Measurement periods in the outskirts get shortened, moved and pushed into the wrong season, usually because something upstream slipped. When that happens the numbers are still worth having, but they no longer support the comparison they were designed for. Say so in the report, in the same paragraph as the figure rather than in a footnote, and state what the shortened window can and cannot show. A qualified result that is trusted is worth more than a clean one that quietly is not.
Say what you found, including when nothing moved
Communication is the third part of this step and the one most easily postponed. Four audiences have a claim on the results. The councils that each adopted their own part of the plan need to see their own commitments tracked, in the form they voted on. The coalition needs enough detail to keep making decisions together. The operator needs the usage picture early enough to act on it. And residents, who were told a service was coming, need to hear how it went, including from an area where a previous promise was not kept.
Publish the results that did not move. An outskirt that only ever hears about successes learns that the reporting is promotional, and the next plan starts from a worse position than this one did. A negative result that is explained, with the three questions above answered honestly, is also the most transferable thing a living lab produces, and it is the raw material the last step works with.